 EPUBLab
Converting a Japanese PDF to EPUB
Updated:
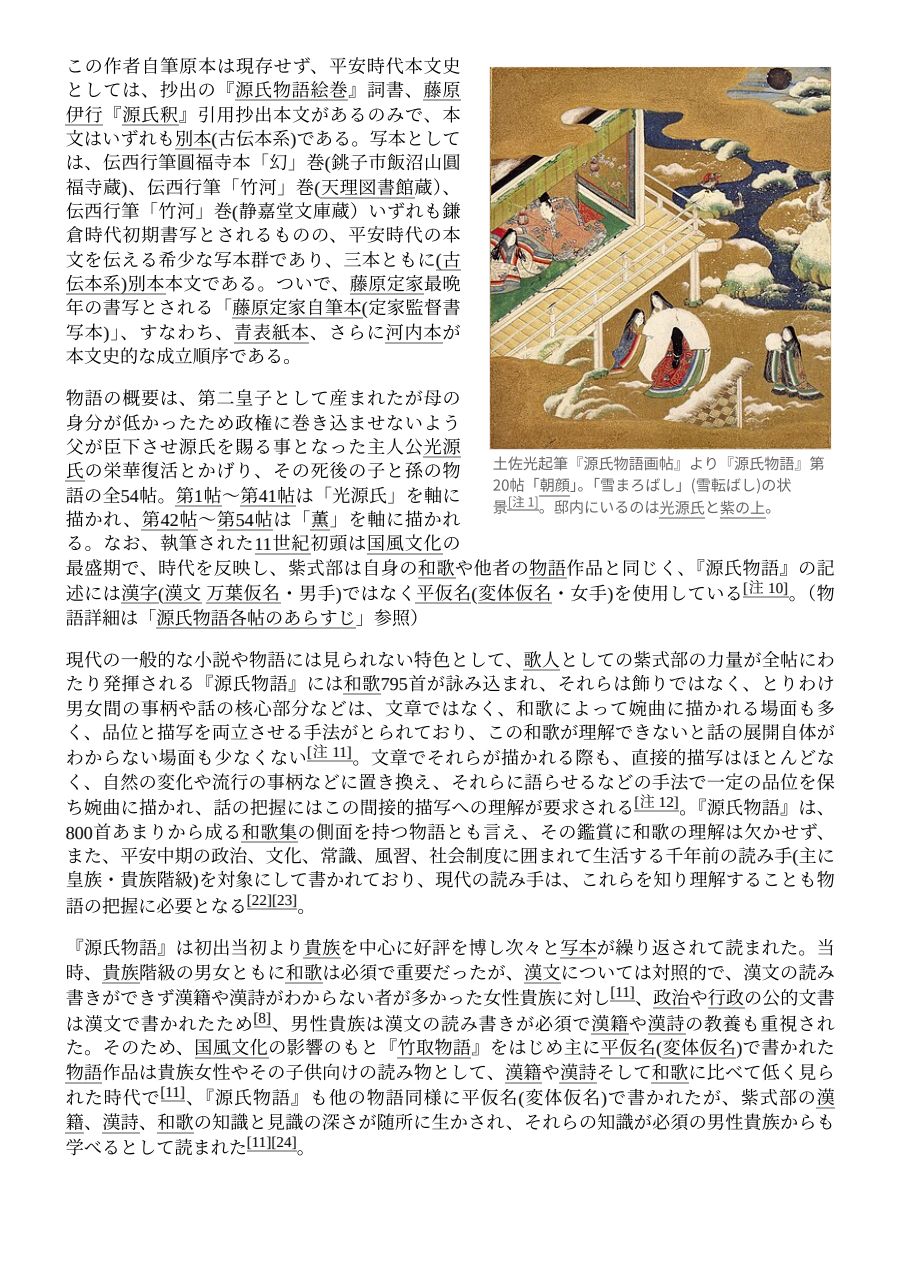
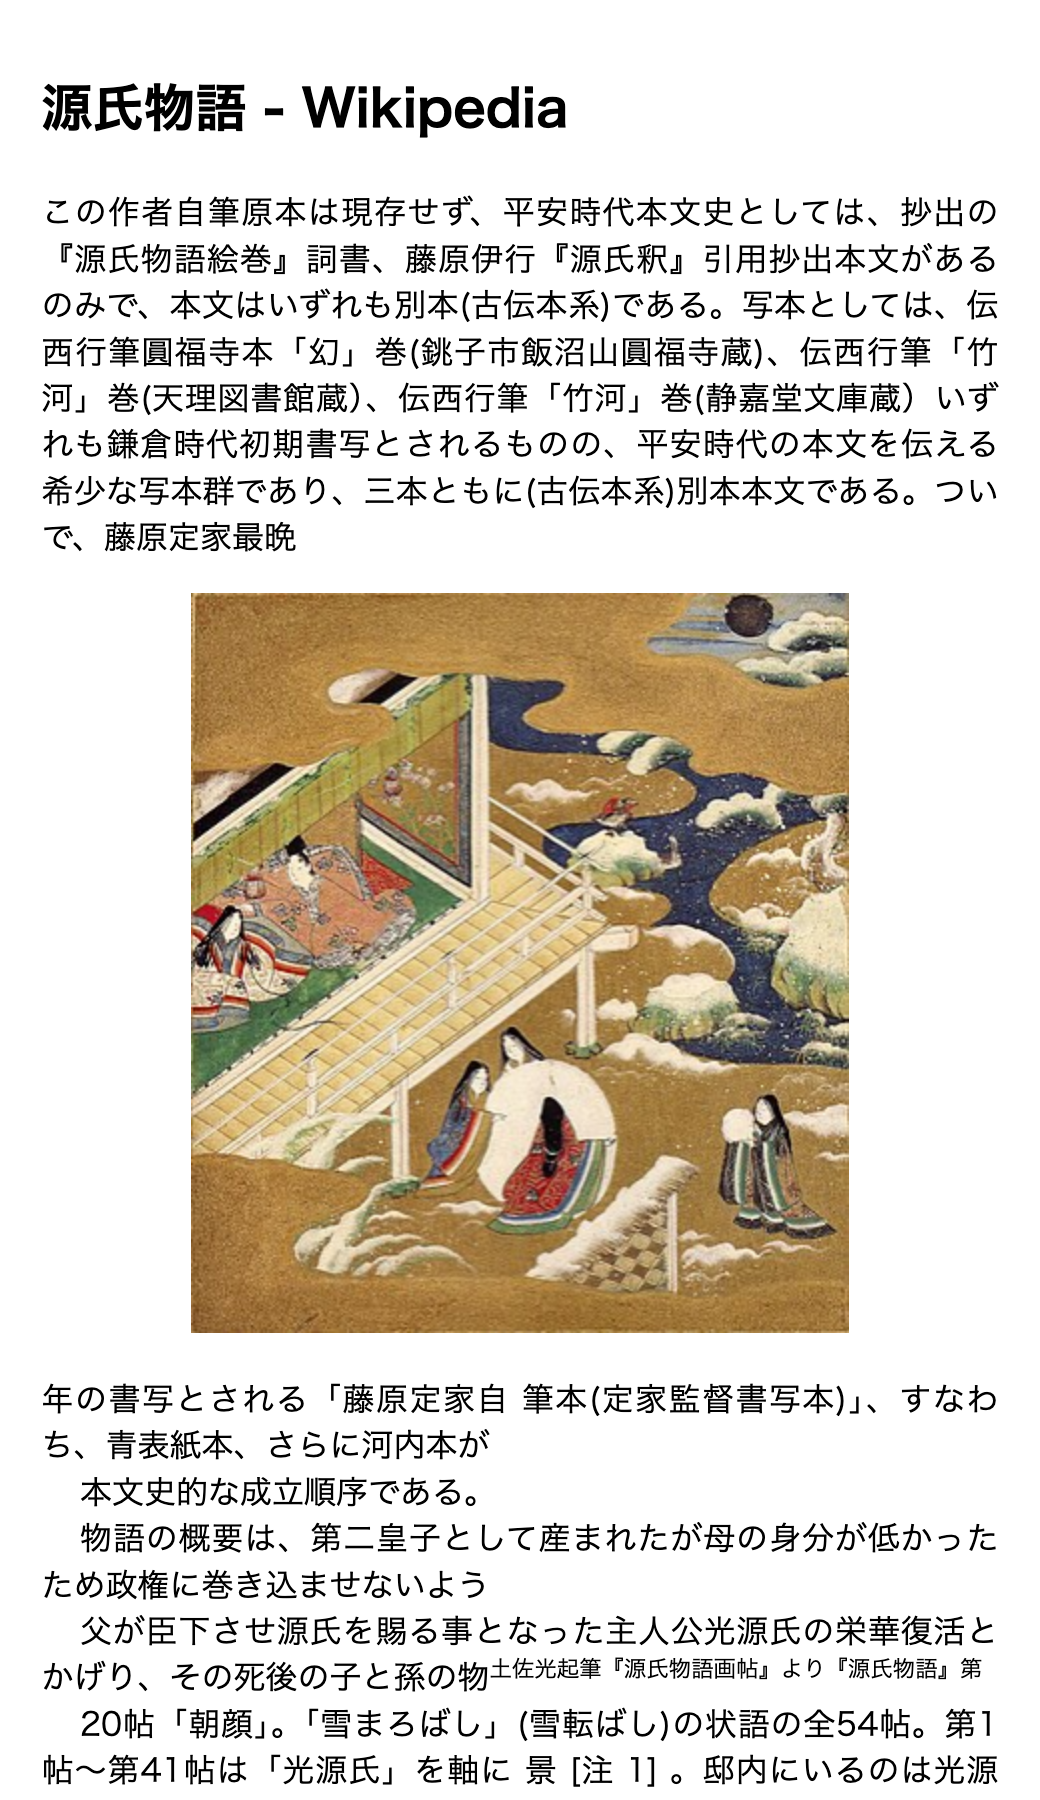
Japanese text has no spaces between words, so joining lines and paragraphs needs different rules than Latin text. On a Japanese Wikipedia article the EPUBLab engine joins CJK lines without inserting spaces.
Original and result
CJK text without spaces between words, mixed with Latin script and numbers.
Download source PDF Download the sample EPUB
Source and licence
- Document
- Wikipedia (Japanese): The Tale of Genji
- Licence
- CC BY-SA 4.0 (text); images under their own licences
- Pages
- 67
- Traits
- text PDF, one column, Japanese, CJK
Settings used
- Engine: epublab-core, build of 2026-11-03 (the one measured in the benchmark).
- Pages: the whole document.
- Options: none. The engine has no per-document settings yet; the same defaults apply to every file.
Validation and results
EPUBCheck EPUBCheck on our EPUB: 0 errors, 0 warnings.
| Engine | 8-gram recall |
|---|---|
| EPUBLab engine (EPUB output) | 0.963 |
| EPUBLab engine (plain text) | 0.963 |
| pdf_oxide · extract_text | 0.970 |
| pdf_oxide · to_plain_text (XY-cut) | 0.970 |
| pdf_oxide · Markdown | 0.797 |
| PDFium · text().all() | 0.952 |
| OpenDataLoader PDF (local mode) | 0.942 |
| pdftotext (Poppler) | 0.965 |
Limitations we observed
- The source is horizontal text; vertical (tategaki) books have not been tested yet.
- pdf_oxide and pdftotext score slightly higher than our engine on this document.